Three tutorials walk through the challenge, from the clinical problem to the engineering. Each one links to a video walkthrough.
Therapeutic Odysseys
The clinical motivation, challenge structure, phase timelines, and the expected inputs and outputs.
Watch the overview → Part 2 · EvidenceBiomedical Resources
How clinicians hunt for treatments today, and the databases a model can query for the same evidence.
Browse the directory → Part 3 · EngineeringCompute & Model Access
GCP environments, Hugging Face for models and data, and the concepts behind a long report that stays grounded in citable evidence.
Get building →Part 1: Therapeutic Identification Workflows
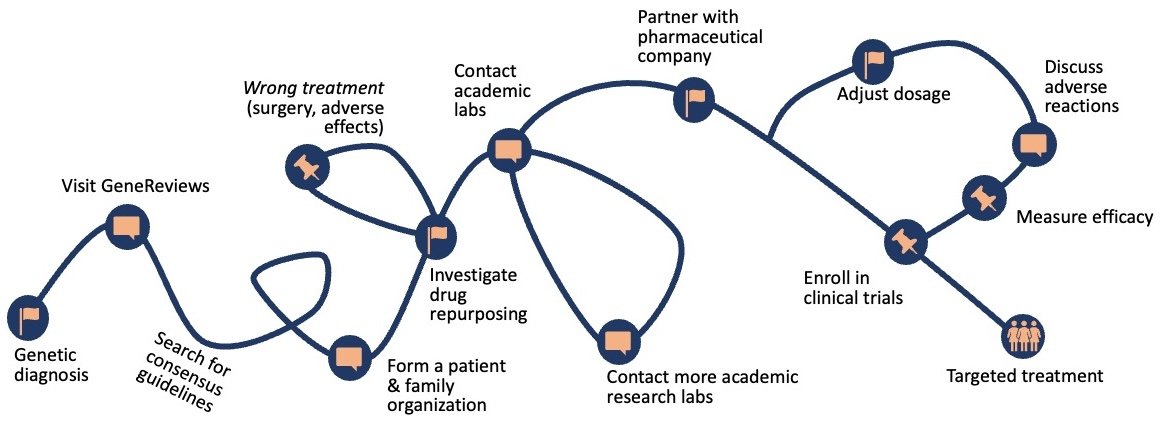
Finding treatments for patients with rare genetic disease diagnoses is a long, frustrating, largely manual process.
Part 2: Biomedical Resources
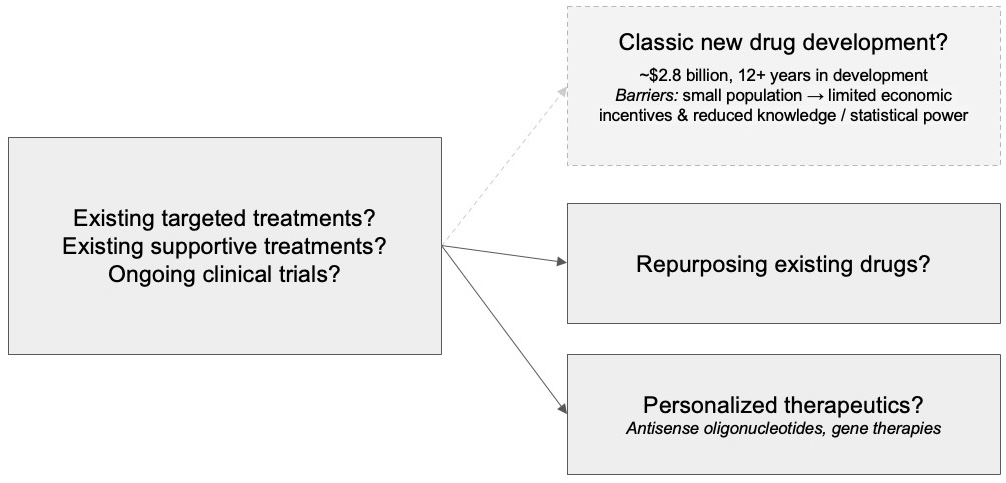
Once a clinician receives a genetic testing report with a confirmed diagnostic variant, the immediate next steps are to identify whether there are:
★ Resource Directory (Nonexhaustive)
• Variant eligibility calculator and accompanying video troubleshooting
Part 3: Computational Resources
1 Hugging Face
Hugging Face is a universal hub for models, data, and deployment — and the place where challenge submissions are shared as Spaces.
2 Challenge-Relevant Concepts
The final challenge is long-form generation grounded in real facts: a narrative actionability report in which every claim carries a source an expert can open and check. Scoring rewards factual accuracy, traceable evidence, and honest calibration, and penalizes confident claims that turn out to be wrong (scoring criteria).
How to build a system that goes and finds the required evidence.
- The core "loop" pattern that an effective solution orchestrates is: pick a tool, see the result, decide what to do next. Anthropic wrote a post about building effective agents, where this simple loop structure can beat a fully prespecified framework.
- Each required section in the Actionability Report asks different questions of different sources, so sections can be researched separately and then assembled.
- Example: AI-Tx Challenge AI Agent Demo on Hugging Face
- MCP is how an agent reaches a source and is the standard interface for exposing tools and data sources to an LLM from any provider.
- Learn how to build MCP Servers with Gradio
- Example: ClinicalTrials.gov MCP server on Hugging Face: embeddings of the "brief description" column from the entire ClinicalTrials.gov database
- Example: PubMed Medline MCP server & Gradio demo on Hugging Face: embeddings of the description/abstract of every article on PubMed
- Once the right tool for the job is decided, you will plan a query, call the live API on that trusted knowledge base, read what comes back, and potentially query again until there is evidence that supports a claim.
- You should always prefer live records to a static snapshot. For example, your actionability report has to know whether a clinical trial is still recruiting or whether a label has been revised, and its citations have to resolve to a specific accession.
- A prebuilt index is a fine way to surface information quickly, but you should pull the live record before you rely on what it says.
- Example: Almanac, NEJM AI
How to check what your system wrote before the expert panel does.
- Use a simple script (rather than tokens) to walk the headings of your generated markdown actionability report to ensure that every required section is present and in order, with each action filed under exactly one heading and never repeated across sections.
- Note that Prioritization & Calibration of proposed action items is more nuanced. Be sure to think about how to judge whether certain evidence is compelling, and how severe contraindications and precautions are.
- Never cite a reference that doesn't support the claim is an explicit requirement, and a plausible-looking citation that says something subtly different is the easiest way to lose points on Factual Accuracy and Evidence & Justification. Since LLMs are notorious for hallucinating citations, use specialized retrieval tools, and/or aim to generate each claim together with its source, and implement a separate pass to confirm that every cited record genuinely entails the claim. Drop or soften claims where these checks fail.
- Remember that LLMs are prone to the same bias as search engines, where pertinent citations behind paywalls are not surfaced, and search-engine-optimized articles from unreputable or predatory journals are presented as fact.
- Long-form factuality in large language models (Wei et al., 2024) breaks a long response into atomic facts and checks each one against search results.
- Some inference APIs can return generated spans already linked to their source documents, e.g. Claude's citations.
- Consider approximating the expert rubric locally by having a strong model score drafts against the same five dimensions before you submit.
- Judging LLM-as-a-Judge (Zheng et al., 2023) on where automated judges agree with human experts and where they diverge
- RAG evaluation cookbook on Hugging Face